
Scale inference behind an Ingress
This guide demonstrates how to scale inference workloads exposed through Kubernetes Ingress based on incoming HTTP traffic. You’ll deploy a sample model with an Ingress resource, configure a ScaledObject, and see how Kedify automatically manages traffic routing for efficient load-based scaling.
Architecture Overview
Section titled “Architecture Overview”For inference workloads exposed via Ingress, Kedify automatically rewires traffic using its autowiring feature. When using the kedify-http scaler, traffic flows through:
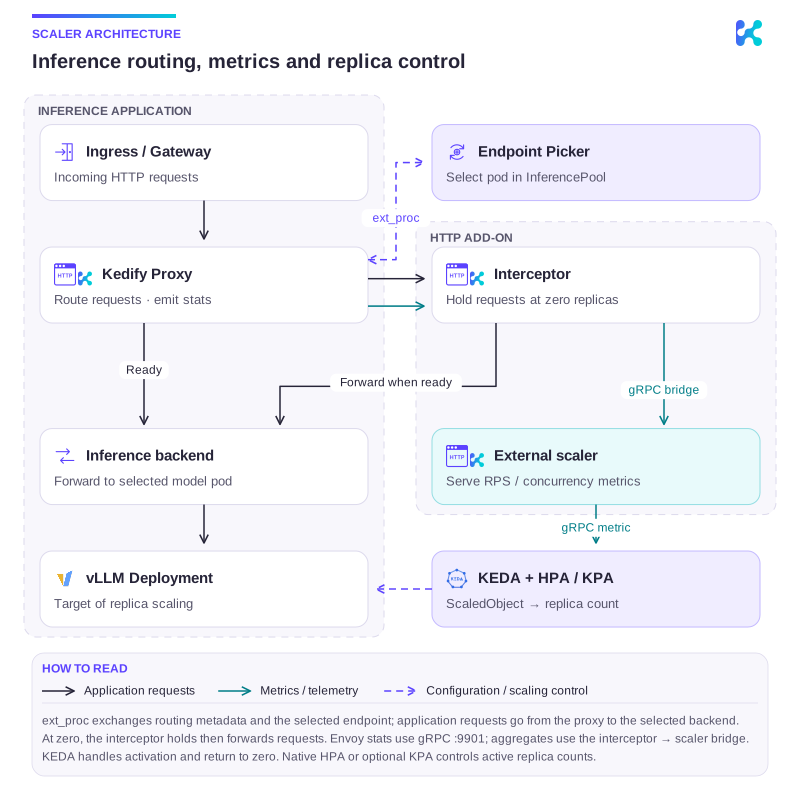
Diagram description
Ingress requests reach Kedify Proxy, which exchanges ext_proc messages with the Endpoint Picker to select an InferencePool endpoint. The proxy forwards request traffic to the model backend, using the interceptor while activating from zero. HTTP statistics feed the external scaler, and KEDA with HPA or KPA scales the vLLM Deployment.
The kedify-proxy intercepts traffic, collects metrics, and enables informed scaling decisions. When traffic increases, Kedify scales your application up; when traffic decreases, it scales down—even to zero if configured.
The kedify-proxy also interacts with inference-scheduler also called Endpoint Picker (EPP) which is a standalone deployment that helps select the proper inference instance that is most likely to provide a correct answer taking into consideration things like KV cache hits.
See HTTP Scaler for inference section to further understand the architecture.
Prerequisites
Section titled “Prerequisites”- A running Kubernetes cluster (local or cloud-based).
- The
kubectlcommand line utility installed and accessible. - Connect your cluster in the Kedify Dashboard.
- If you do not have a connected cluster, install Kedify using the Helm installation guide.
- Install hey to send load to a web application.
Step 1: Install Gateway API Inference Extension CRDs and Create Namespace
Section titled “Step 1: Install Gateway API Inference Extension CRDs and Create Namespace”Install the necessary CRDs to your cluster:
kubectl apply -f https://github.com/kubernetes-sigs/gateway-api/releases/download/v1.4.0/standard-install.yamlkubectl apply -f https://github.com/kubernetes-sigs/gateway-api-inference-extension/releases/download/v1.1.0/manifests.yamlkubectl create namespace inferencepoolStep 2: Deploy Inference Scheduler (EPP)
Section titled “Step 2: Deploy Inference Scheduler (EPP)”helm upgrade --install inferencepool oci://registry.k8s.io/gateway-api-inference-extension/charts/inferencepool --version=v1.1.0 --namespace=inferencepool --wait --timeout=5m --values=inferencepoolvalues.yamlThe whole values YAML:
# ref https://github.com/llm-d/llm-d/blob/main/guides/simulated-accelerators/gaie-sim/values.yamlinferenceExtension:  replicas: 1  image:    name: epp    hub: registry.k8s.io/gateway-api-inference-extension    tag: v1.1.0    pullPolicy: Always  extProcPort: 9002  pluginsConfigFile: "default-plugins.yaml" # using upstream GIE default-plugins, see: https://github.com/kubernetes-sigs/gateway-api-inference-extension/blob/main/config/charts/inferencepool/templates/epp-config.yaml#L7C3-L56C33
# Monitoring configuration for EPP monitoring: interval: "10s" # Service account token secret for authentication secret: name: sim-gateway-sa-metrics-reader-secret # Prometheus ServiceMonitor will be created when enabled for EPP metrics collection prometheus: enabled: falseinferencePool: targetPortNumber: 8000 apiVersion: inference.networking.k8s.io/v1 # use beta API version for inference modelServerType: vllm modelServers: matchLabels: llm-d.ai/inferenceServing: "true"inferenceExtension.image.name(epp): Specifies the image name of the external processor.inferenceExtension.image.hub(registry.k8s.io/gateway-api-inference-extension): Specifies the registry to fetch the image for the external processor.inferenceExtension.image.tag(v1.1.0): Specifies the external processor image tag.inferenceExtension.extProcPort(9002): Specifies the port where the external processor listens to requests.inferenceExtension.pluginsConfigFile(default-plugins.yaml): Specifies the config file for the external processor.inferencePool.modelServerType(vllm): Specifies the type of model server engine used, in this case it is vLLM.inferencePool.modelServers.matchLabels(llm-d.ai/inferenceServing: true): Specifies the labels for the pods to match the inferencepool selector.
You should see the inferencepool created and the EPP:
kubectl get po -n inferencepoolkubectl describe InferencePool -n inferencepoolStep 3: Deploy llm-d Example
Section titled “Step 3: Deploy llm-d Example”Now, install the following helm chart:
helm repo add llm-d-modelservice https://llm-d-incubation.github.io/llm-d-modelservice/helm repo update llm-d-modelservicehelm upgrade --install vllm llm-d-modelservice/llm-d-modelservice --version=v0.3.0 --namespace=inferencepool --values=pdvalues.yamlThe values YAML:
# This values.yaml file creates the resources for CPU-only scenario# Uses a vLLM simulator# When true, LeaderWorkerSet is used instead of Deploymentmultinode: false
modelArtifacts:  # name is the value of the model parameter in OpenAI requests  name: random/model  labels:    llm-d.ai/inferenceServing: "true"    llm-d.ai/model: random-model  uri: "hf://{{ .Values.modelArtifacts.name }}"  size: 5Mi
routing:  servicePort: 8000
  proxy:    secure: false    image: ghcr.io/llm-d/llm-d-routing-sidecar:v0.3.0
# Decode pod configurationdecode:  replicas: 1  containers:    - name: "vllm"      image: "ghcr.io/llm-d/llm-d-inference-sim:v0.3.0"      modelCommand: imageDefault      ports:        - containerPort: 8200 # from routing.proxy.targetPort          protocol: TCP      mountModelVolume: true
# Prefill pod configurationprefill: create: falsemodelArtifacts.labels(llm-d.ai/inferenceServing): Specifies the labels for the pods to match the inferencepool selector.modelArtifacts.name(random/model): The name for the model to use on inference requests.routing.servicePort(8000): The port where vLLM sidecar proxy listens for requests.decode.containers.image(ghcr.io/llm-d/llm-d-inference-sim:v0.3.0): The image for decode. In this example, it is a simulator.decode.containers.ports.containerPort(8200): Port for vLLM container for the sidecar proxy to forward trafficprefill.create(false): Since we want a single vLLM instance, we don’t need a prefill instance.
You should see the vLLM (decode) pod in the inferencepool namespace.
Step 4: Service and Ingress
Section titled “Step 4: Service and Ingress”In order for the kedify-proxy to behave as expected we need to create an equivalent Service that targets the same labels as the inferencepool created earlier.
kubectl apply -f inferencepoolservice.yamlThe inferencepool service YAML:
apiVersion: v1kind: Servicemetadata: name: vllm-llm-d-modelservice-inference-svc namespace: inferencepool labels: llm-d.ai/inferenceServing: "true" inferencepool: inferencepoolspec: ports: - port: 9002 targetPort: 8000 protocol: TCP name: http selector: llm-d.ai/inferenceServing: "true"---apiVersion: networking.k8s.io/v1kind: Ingressmetadata: name: inferencepool-ingress namespace: inferencepoolspec: rules: - host: application.keda http: paths: - path: /v1 pathType: Prefix backend: service: name: vllm-llm-d-modelservice-inference-svc port: number: 9002Step 5 Apply ScaledObject to Autoscale
Section titled “Step 5 Apply ScaledObject to Autoscale”kubectl apply -f scaledobject.yamlThe ScaledObject YAML:
kind: ScaledObjectapiVersion: keda.sh/v1alpha1metadata: name: inferencepool namespace: inferencepoolspec: scaleTargetRef: apiVersion: apps/v1 kind: Deployment name: vllm-llm-d-modelservice-decode cooldownPeriod: 600 minReplicaCount: 1 maxReplicaCount: 2 fallback: failureThreshold: 2 replicas: 1 advanced: restoreToOriginalReplicaCount: true horizontalPodAutoscalerConfig: behavior: scaleDown: stabilizationWindowSeconds: 600 triggers: - type: kedify-http metadata: hosts: application.keda pathPrefixes: /v1 service: vllm-llm-d-modelservice-inference-svc port: "9002" scalingMetric: requestRate targetValue: "5" granularity: 1s window: 1m trafficAutowire: ingress inferencePool: inferencepooltriggers.metadata.inferencePool(inferencepool): Specifies the inferencepool name to use.triggers.metadata.service(vllm-llm-d-modelservice-inference-svc): References the service equivalent to the inferencepool.spec.scaleTargetRef.name(vllm-llm-d-modelservice-decode): Specifies deployment to scale.
For inference workloads we want to scale decode workloads as these can be more resource-intensive.
Step 6: Test Autoscaling
Section titled “Step 6: Test Autoscaling”First, let’s verify that the application responds to requests:
# If testing locally with k3d (if testing on a remote cluster, use the Ingress IP or domain)curl -H "Host: application.keda" http://localhost:9080/v1/modelsIf everything is working, you should see a successful HTTP response:
{ "data": [ { "created": 1762202649, "id": "random/model", "object": "model", "owned_by": "vllm", "parent": null, "root": "random/model" } ], "object": "list"}You can also send a completions query.
curl -X POST http://localhost:9080/v1/completions \ -H "Host: application.keda" -H 'Content-Type: application/json' \ -d '{ "model": "random/model", "prompt": "once upon a time" }'Now, let’s test with higher load:
# If testing locally with k3d (if testing on a remote cluster, use the Ingress IP or domain)hey -n 10000 -q 1000 -c 150 -m POST -host "application.keda" -d '{ "model": "random/model", "prompt": "once upon a time" }' http://localhost:9080/v1/completionsAfter sending the load, you’ll see a response time histogram in the terminal:
Response time histogram: 0.001 [1] | 0.038 [2579] |■■■■■■■■■■■■■■■■ 0.076 [9] | 0.113 [6392] |■■■■■■■■■■■■■■■■■■■■■■■■■■■■■■■■■■■■■■■■ 0.151 [37] | 0.188 [362] |■■ 0.226 [474] |■■■ 0.264 [0] | 0.301 [31] | 0.339 [0] | 0.376 [15] |Next steps
Section titled “Next steps”You can explore the complete documentation of the HTTP Scaler for more advanced configurations, including other ingress types like Gateway API, Istio VirtualService, or OpenShift Routes.
Continue with this topic
Section titled “Continue with this topic”Reference: HTTP scaler and inference configuration.